Showing posts sorted by relevance for query cloud. Sort by date Show all posts

Sunday, June 25, 2023

The Cloud and High Availability

One of my new favorite podcasts is RunAsRadio with Richard Campbell. The June 14, 2023 edition was "High Availability in 2023 with Allan Hirt".


You can see Allan Hirt's credentials on LinkedIn.

Here's the synopsis of the podcast:
What does high availability look like in 2023? Richard chats with Allan Hirt about his work with high-availability solutions today - not just on-premises but also in the cloud. Allan talks about the frustration folks had with moving workloads in the cloud during the pandemic panic, lift-and-shifting workloads focusing on getting things working quickly rather than cost-effectively. The results can be costly, to the point where some folks considering moving back off the cloud again - but does that make sense? Allan talks about creating high availability efficiently wherever you want to run your workloads!
Richard and Allan covered availability as manifested in the cloud. Allan is a SQL Server guru who works for Pure Storage.

Here are some excerpts.
And cloud isn't a silver bullet for availability.
And the cloud doesn't eliminate traditional availability issues.
And the cloud introduces new issues.
And old issues don't go away.
And monitoring gets even more important.
But cloud providers likely provide higher availability than you could.
But just moving to the cloud doesn't guarantee more benefits.
If you're not good at on premises, you won't be any better on the cloud.
AWS - Amazon Web Services
GCP - Google Cloud Platform
IaaS - Infrastructure as a Service
PaaS - Platform as a Service
SCOM - Microsoft System Center Operations Manager
NOC - Network Operations Center

Sunday, November 10, 2019

Cloud Management Skills

Recently McAfee published a report on cloud adoption and risk. The Register did a review of the McAfee study.

The Register concluded:
The ongoing rash of data leaks caused by misconfigured clouds is the result of companies having virtually no visibility into how their cloud instances are configured, and very little ability to audit and manage them.
That's really scary. But it supports my concerns that moving workload to the cloud doesn't eliminate work/effort, i.e. manpower, but rather changes the skills required.

An organization should thoroughly understand the skills change that moving to the cloud brings.

These changes may be addressed with training but may require changing personnel to acquire the appropriate skills. These changes and the change management time and effort should be incorporated in the project timeline and budget for cloud implementation.

McAfee observed:
It’s possible the speed of cloud adoption is putting some practitioners behind.
The number 1 cause of cloud security issues noted by McAfee was "Lack of staff with the skills to secure cloud infrastructure."


That entire list is a good reference when considering moving workload to the cloud.

Sunday, October 11, 2015

Cloud Security

I follow a number of CIO-orientated blogs and this article popped up recently:
Why promises about cloud security make me uneasy
I couldn't have said it better myself.

The entire article is worth reading but I'll try to pull out the highlights here.
Cloud companies will tell you that their products and services are secure and you can use security products to ensure that your data and applications are secure. I am a bit skeptical.
I can maintain and monitor use and access to my user base and interrogate logs of application use however I lack key visibility when in comes to the cloud...
While many organizations struggle to "maintain and monitor use and access" at least they control their own destiny. In a cloud environment you will "lack key visibility."

You'll recall my observations in a prior post.
...as a CIO are you comfortable with this level of opacity to service failures?
From the referenced article:
I lack control of the cloud and am dependent on a third party vendor for disclosure and transparency ...
Not a comfortable position for a CIO.

To raise both sides of this topic, if you or your organization are not able to "maintain and monitor use and access" maybe delegating that to a cloud provider is the prudent thing to do.

Just make sure your boss is on board with your decision. And that you've got the mobile number of your cloud salesperson.

Sunday, January 01, 2017

Rumbling Clouds

I've written several times about "cloud" availability/reliability. A recent article on Microsoft's outlook.com service brought this back to my attention. This is Microsoft's free service so there's not really a lot of room to complain. This discussion is to compare the cloud solution to a self-hosted solution.

Microsoft has a status page which was getting updated regularly which is good but the details were a little light, e.g. "focused on remediation" and "users may be able to access the service by logging in to their Outlook.com accounts with a web browser as an alternative method". The problem existed almost a week.

Again this is a free service but these are situations you need to consider as you explore moving a service to the cloud.

Go read some of the comments:
When you go cloud hosted you are subcontracting your responsibility to a third party.
That third party may be much more capable than your IT budget will allow
I've got better reliability and almost the same service and functions as my company OWA account, free of charge as well.
Cloud is a way to free up the expense of operating your own IT services.
But putting your eggs into the hands of Microsoft, Google, Amazon or any other single entity to which you represent 0.00000000001% of their annual income is a stupid idea.
Realize that you are less than a rounding error to the cloud provider.
I don't hear many people talk about ... the time it takes to repair a massive amount of infrastructure even when know how and have a fix available. I expect this to only get worse as the cloud continues to grow.
Clouds by nature are BIG. Big things take a long time to fix. Be prepared for that.

Sunday, March 11, 2018

It's Not Our Fault

I follow the Internet Storm Center's diary. Recently one of the entries related a situation with a personal NAS (Network Attached Storage) with terabytes of data. It was configured with RAID5. The NAS vendor offered a cloud backup service that he used.

He had a detailed backup plan consisting of:
  • a daily backup to a cloud storage provider
  • a monthly backup to an external disk (physically stored away from the source)
  • a file restore test performed every month (ex: restore file ‘x' backup at time ‘t’)

While this diary is about a personal situation the lessons apply to enterprise as well.

The power failed in his area and the NAS crashed hard. He reloaded the operating system and rebuild the RAID5.

No data was lost.

But then he had to “relink” the existing cloud backup with the new backup task on the NAS. That  failed with strange error messages saying that some files were not found.

After the normal "Turn it off and back on" with no success the vendor responded:
Thank you to try to log on your cloud service console to check if your files are available. If they are not available, please contact your cloud service support to get more help. We already notified them about this issue and we received a lot of complaints from other customers who are facing the same issue. You should try to see with them how to recover your files, if possible...
Remember that "your cloud service" was arranged by the NAS vendor.

Yep, his cloud backup was lost (1.5TB of data).

What if that had been YOUR enterprise data?

Have a plan. Have a backup to that plan. Test it. Test it again.

Sunday, December 01, 2019

A Fool and His Data Are Soon Parted

Azure just keeps having problems. And a recent incident happened while their CEO was speaking at a conference in Sydney "focused on showing off how Microsoft's cloud technology can have a transformative impact on businesses."

While it's easy to pile on with Azure, the situation is endemic to the cloud environment. Not withstanding my recent post, cloud implementations still carry significant risks. The news.com.au article states:
While cloud technology can have a massive impact on the way businesses run, as we are currently witnessing, it can also create new headaches when things don’t work how they’re supposed to.
And this was the second Microsoft cloud outage in 24 hours.

Really worrisome to me is that the Microsoft Office portal wasn't responsive.


As usual the comments are the most interesting. Clearly some are trolls but some are really to the point.
captain goodvibes
Anyone who trusts cloud technology to store data risks it disappearing into thin air. The only way to safely store data is on a hard drive. To paraphrase an old adage, a fool and his data are soon parted.
Anthony
The problem is for a lot of organisations is that they are too small to safely and economically run their ICT. Large vendors can provide resilience, security, and responsive services easier. And no, I don’t work for Microsoft, but I have worked in outsourcing :-) so I know the numbers
HG
If your business model is a monopoly, make sure your cr*p works.
Gordon
I spent most of my career in IT, I just do not understand why anyone would trust another company to manage all of their business critical data off site....
Yeah, worry about your business critical data.

Sunday, August 16, 2026

Cloud Single Points of Failure

Probably one of my most frequent blog topics is "cloud". I'm sure that you've all read and incorporated my suggestions in your solutions. You're welcome.


Recently, a twist arose that I hadn't considered.

You've certainly taken advantage of your cloud providers geographic separation. But did you ask the really tacky questions?

In July, Google Cloud had an "incident" that took down customer workloads that were spread across multiple geographic "zones."

It turns out that some of Google Cloud services are tied to a single datacenter.

But YOU certainly inquired about that when you contracted to place your workload across different zones and regions to ensure resilience. And a requirement that all of the cloud's services you require were redundant in your contract with service level commitments.

Didn't you?

Now you know.

The details are here (archive.org) and here (archive.org).

Sunday, July 27, 2014

Storm Clouds

During the last week in June, several of Microsoft's cloud services had outages. This is not picking on Microsoft as Google had outages as well. It's just that I found a good discussion about the impact of the Microsoft outages.


In outages this week, Microsoft’s online Exchange service was down for nine hours, crippling Office 365 and hosted Outlook accounts across North America and Mexico, just after its unified communications service also crashed.

Aside from the fact that entire businesses were left unable to read or write email in the Office 365 downtime, users were also pretty ticked off with Microsoft’s response. User Trec posted on the Office 365 community page:
Tried to contact support by phone, and after half hour, the call was dropped on both occasions. It seems the support guys are saturated and there are not enough staff for an issue like this one.
While Jim1001 said:
Our entire corporation cannot send or receive emails from Outlook (Office 365 Exchange) or even the OWA web browser as of 8AM MST time this morning June 24, 2014! I have never seen a world-wide email go down like this.
And MacBuffalo said:
Office365 is beginning to look like a very poor choice for mission critical services.
Lync Online, which provides VoIP, corporate IM and video conferencing had also briefly crashed two days before, leaving some customers, like ThomasGallaway, suffering a double whammy:
Down for 3 hours now. When going to Calendar outlook freezes. Send/receive works on iPhone. This sucks as we were hit yesterday by the lync outage. Today email. What's going on M$?


Just as in previous cloud services outages the provider (just happened to be Microsoft in this case) couldn't handle responding to customers about the situation. This still makes me worry about putting a corporation's systems in a public cloud where the provider can't provide the same level of accountability as internal services.

Unlike previous cloud services outages Microsoft's Rajesh Jha, Corporate Vice President, Office 365 Engineering has offered an explanation of the outage. The Corporate Vice President of Customer Service has been quiet.

My previous posts on this topic:

     When Clouds Go Bump
     When Clouds Go Thump
     Lessons from the Cloud
     When Clouds Go Bump Revisited
     To Be Fair
     To Be Fair, Again
     To Be Fair, Again and Again

Sunday, August 22, 2021

If You’re Going to Use the Cloud

... for Pete's sake, please use its strengths.

You know I have mixed opinions on the "cloud" depending on the size and capability of your organization.

An example of leveraging the cloud's strengths is in a recent article I saw from KnowBe4 entitled "Can the Microsoft 365 Platform Be Trusted to Stop Security Breaches?"

KnowBe4 referenced an article from Hornetsecurity entitled "1 of every 4 companies suffered at least one email security breach, Hornetsecurity survey finds." (Don't click on that just yet.)


Realizing that everybody has an agenda, let's look at these articles.

KnowBe4 calls out the following findings:
  • 33% of organizations are not using Microsoft’s multi-factor authentication (MFA)
  • Of those using MFA, 55% of organizations are not using Conditional Access which scrutinizes connection requests beyond just providing credentials and additional authentication factors
  • Only 43% leverage Microsoft’s data loss prevention policies to keep data from leaving the organization
  • 68% of organizations expect Microsoft to keep email safe from threats
This is my point. If you're going to use a cloud solution such as Microsoft 365, leverage its capabilities. Even if they are premium services, they're probably NOT services you could deliver yourself.

KnowBe4's recommendation: Have your "Users ... undergo continual Security Awareness Training."

By the way, that's KnowBe4's business model - training users. And that's a good thing.

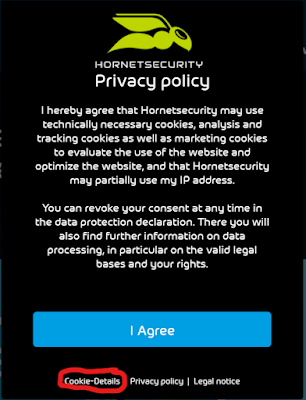
Now, before you click on Hornetsecurity's link, get ready for a pretty aggressive privacy policy.


That almost scared me off. But just click on "Cookie-Details" and slide everything to "Off".

In addition to the points that KnowBe4 raised from Hornetsecurity's study, Hornetsecurity has one more finding: "An impressive 82% of all our respondents who use third-party email security solutions reported no breaches."

I'll bet you can guess what Hornetsecurity sells.

Regardless of the various agendas, the Hornetsecurity study is solid and the findings valuable. Take them into consideration for your Microsoft 365 implementation.

And consider the value-add capabilities of any cloud solution you implement.

Sunday, May 10, 2015

Big Blue Clouds


I've recently added Ben Kepes to my reading list. The Forbes web site is awfully heavy with clutter but I let Adblock Plus do its thing.

A recent article was about IBM (hence "Big Blue" in the title) and their cloud activities.

Ben drug out all the old stories, e.g. Watson winning Jeopardy and "nobody ever got fired for buying IBM" but went on to relate a conversation that he had with Robert LeBlanc, SVP of IBM’s Cloud business.

LeBlanc's comments are full of platitudes - "No enterprise is going to lift trillions of dollars of existing assets into the cloud." and "New development will happen in the cloud, but existing assets will stay put."

Then LeBlanc got into classic IBM speak. Kepes asked him if IBM "would begin to zero rate international traffic." LeBlanc's response was that "high availability is important."

Huh?

Kepes did call out IBM on their continual claims to be the biggest cloud vendor. "I've not seen any independent commentator who gives their claims any real credence."

Sunday, January 25, 2015

Enterprise Cloud Providers

As you know, I'm a big follower of cloud technology. Early this year I came across an article in the Wall Street Journal.

In this article the WSJ reported on a recent survey by Piper Jaffray of 112 CIOs. Piper Jaffray asked the CIOs to name their preferred public cloud provider.

Amazon Web Services led the responses with a 2 percentage point increase from 33% to 35%. Microsoft's Azure increased from 20% to 21%. IBM Softlayer had the biggest gain increasing from 4% to 6%.

The big loser was Google falling from 12% to 7%.


Reminds me of the old saying that "Nobody got fired for choosing IBM." Or Microsoft.

There's an interesting comparison of Amazon and Microsoft's cloud offerings here.

Sunday, March 15, 2015

Apple Cloud Outage

Now we have a new player in the battle of (un)availability in the cloud. On March 11, 2015 Apple's iTunes store was down for 10 plus hours.


But look closer at that web page. First, we could see that web page unlike one of Microsoft's outages. Second, nothing was down but the App Store. iCloud Account & Sign In - Up. iCloud Backup - Up. iTunes in the Cloud - Up. And on and on.

And Apple acknowledged the same day that the downtime was caused by problems with its DNS setup.

The other cloud players could learn something from Apple.

Sunday, November 29, 2015

Google Cloud Outages

I've written numerous times about cloud availability. Last year I posted about an outage in Microsoft's Azure service.

Some of my comments were:
Recently there was an 11 hour outage of Microsoft's Azure storage services.

Again users were hard pressed to get details on the outage as "the Service Health Dashboard and Azure Management Portal both rely on Azure."
Cloud outages don't have to be like that.

Here're the communications from Google on a pair of recent outages in their cloud services.

Gmail Outage

November 3, 2015 1:21:00 AM PST
We're investigating reports of an issue with Gmail. We will provide more information shortly.
November 3, 2015 1:38:00 AM PST
Our team is continuing to investigate this issue. We will provide an update by November 3, 2015 2:38:00 AM PST with more information about this problem. Thank you for your patience.

This issue is affecting IMAP and SMTP delivery
November 3, 2015 1:48:00 AM PST
Our team is continuing to investigate this issue. We will provide an update by November 3, 2015 2:48:00 AM PST with more information about this problem. Thank you for your patience.

This issue is affecting incoming POP, SMTP and IMAP connections.
November 3, 2015 2:25:00 AM PST
The problem with Gmail should be resolved. We apologize for the inconvenience and thank you for your patience and continued support. Please rest assured that system reliability is a top priority at Google, and we are making continuous improvements to make our systems better.
Four posts in just over one hour.

Google Calendar Outage

November 4, 2015 8:20:00 AM PST
We're investigating reports of an issue with Google Calendar. We will provide more information shortly.
November 4, 2015 9:25:00 AM PST
Google Calendar service has already been restored for some users, and we expect a resolution for all users within the next 1 hours. Please note this time frame is an estimate and may change.
November 4, 2015 10:25:00 AM PST
The problem with Google Calendar should be resolved. We apologize for the inconvenience and thank you for your patience and continued support. Please rest assured that system reliability is a top priority at Google, and we are making continuous improvements to make our systems better.
Three posts in just over two hours.

Everybody is going to have outages. But this is the way to handle them.

Sunday, August 13, 2017

Cloud - Office 365

Sometimes it's just too easy to make fun of a company.

In May 2017 Microsoft had gathered their favorite developers in Redmond for the annual Build conference. The focus of that conference was Microsoft's offerings of Office and Azure.

Yeah, you guessed it. Office 365 went down in the middle of the conference as documented by the Register.

Outages happen to everybody.

What I thought interesting were the comments on the Register post:
Cloud just means somebody else's computer that you have NO control over, and can go down at any time leaving you helpless.
Herby
Cloud: A computing service that signifies you do not know where any outage is, who is responsible for it, who else but you or your organization accesses the data on it, but nobody wants to do without.
Jeroen Braamhaar
Having worked with Cloud products for near 10 years now, I can say that in general they are much more reliable and lower cost than an on prem equivalent. ... [Y]ou do get a much better infrastructure from a company that invests millions/billions and has SLA's around it all than the bit of tin you got from the reseller round the corner.
Babbit55
This situation is kinda like when I was on a conference call with my CIO and his boss the CFO. It wasn't a pleasant discussion. When the call was over my CIO turned to me and said "I don't ever want to have that discussion again."

Don't find yourself or your company in the situation that Microsoft was in. Consider and act on the points in those comments.


Sunday, April 08, 2012

When Clouds Go Bump

There certainly has been a lot of discussion at the CIO level about Cloud Computing. A recent CIO I spoke with was looking at the cloud to help him address his challenges in staffing and running his data center. He and I had deep discussions about his in house alternatives to the cloud. Interestingly while we were having these discussions one of the biggest clouds went bump.

On February 29, 2012 Microsoft's Azure product had a global service failure. Microsoft's Azure Service Dashboard was overwhelmed and pretty much unavailable for hours on end. When it was accessible here is one of the updates approximately 8 hours into the outage:
The restoration steps to mitigate the issue are still underway. This incident impacts Access Control 2.0, Marketplace, Service Bus and the Access Control & Caching Portal in the same regions where Windows Azure Compute is impacted. As a result affected customers may experience a loss of application functionality. Further updates will be published to keep you apprised of the situation. We apologize for any inconvenience this causes our customers.
This is not a Microsoft bashing. In April, 2011 Amazon also suffered a broad failure.

What I want to highlight is that cloud providers are not immune from service failures. They are likely capable of providing more redundant and resilient services than many organizations can provide.

My question is as a CIO are you comfortable with this level of opacity to service failures? Are you willing to answer your users and executives with one-way information flow from a (sometimes available) web page? Would a 10 day service credit make your CEO happy?

Sunday, March 03, 2013

Lessons from the Cloud

While researching the recent Microsoft Azure Storage outage I came across a presentation by Jason Chan of Netflix. While the topic was "Practical Cloud Security" there were a couple of slides that I thought applied to many organizations' situation.

We all remember how Netflix changed their business model several years ago going from mailing DVDs to streaming video online. This resulted in a 37 fold increase in API requests in one year.


Realistically most organizations don't experience that kind of growth but any organization that plans to grow should look for lessons learned.

Prior to the cloud migration Netflix was running their own data centers. Here's what they were doing in their data centers.


Sound familiar?

I especially like the "snowflake phenomenon" metaphor. That means that everything is a one-off. Nothing is reused.

Netflix's vision was to get out of the data center business and into the cloud.
We want to use clouds, not build them.
Their target patterns were much different.


Think about how this transition will reduce your costs and improve your delivery speed.

Maybe you can stream a movie in your spare time.

Sunday, November 23, 2014

More Lessons from the Cloud

There seems to be a recurring theme in my posts about outages in cloud services. While not trying to beat that dead horse there are certainly some lessons to be learned here.

Recently there was an 11 hour outage of Microsoft's Azure storage services.

Again users were hard pressed to get details on the outage as "the Service Health Dashboard and Azure Management Portal both rely on Azure."

I commend Microsoft for owning up to the root problem quickly and succinctly.
"Unfortunately the issue was widespread, since the update was made across most regions in a short period of time due to operational error, instead of following the standard protocol of applying production changes in incremental batches."
     http://azure.microsoft.com/blog/2014/11/19/update-on-azure-storage-service-interruption/
One of the comments summed it up best:
Overdependence.

So much tied into itself that there is no dependency tree - it is a pure network - thus issuing bad changes take down the entire net.

It can be a spectacular update process - minimum to no outage... but only if the updates work.

It also shows a major vulnerability. That central update can take down the entire company if it gets penetrated.

jessepollard
20 November, 2014 12:46
So, lessons...
  1. Diversify - Don't build your notification tool on top of what you're monitoring.
  2. Manage change - Don't let operational error bite you in the a**. Your execution has to be perfect. Users are unforgiving.
These don't apply just to cloud solutions. They apply just as much to your internal solutions.

My previous posts on this topic:

Storm Clouds
When Clouds Go Bump
When Clouds Go Thump
Lessons from the Cloud
When Clouds Go Bump Revisited
To Be Fair
To Be Fair, Again
To Be Fair, Again and Again

Update: Microsoft has published a thorough analysis of the problem with the corrective action. Good job Microsoft!

Sunday, March 05, 2017

Cloudy Day

To some I'm sure that March 1st felt like April 1st. Really, that couldn't be happening? Amazon's S3 (Simple Storage Service) went down in their Eastern Region (Ok, it just had "high error rates").

But there are a couple of lessons to be learned from this.

First, it seems nobody is listening to me.

Cloud services aren't magical (even Apple's). They rumble. They go bump.

Don't abdicate your responsibilities to the cloud provider. If you need high availability make sure that that is what your contract guarantees.

In the March 1st S3 outage either lots of customers didn't feel they needed high availability or they misunderstood what they contracted for.

Make sure you are not surprised like "Docker's Registry Hub, Trello, Travis CI, GitHub and GitLab, Quora, Medium, Signal, Slack, Imgur, Twitch.tv, Razer, heaps of publications that stored images and other media in S3, Adobe's cloud, Zendesk, Heroku, Coursera, Bitbucket, Autodesk's cloud, Twilio, Mailchimp, Citrix, Expedia, Flipboard, and Yahoo! Mail (which you probably shouldn't be using anyway)." (source)

At the same time don't over buy. One of my customers was considering migrating their on-premise servers to Azure. As part of their on-premise setup they had a specific backup system and service. When I investigated Azure's service commitments I found that Azure's committed backup and availability met my customers needs and the customer could discontinue their backup system and service.

By the way Amazon did a thorough post mortem on the outage.

Second (and more concerning since they should know better), even Amazon had highly visible services down.

Reminiscent of one of Microsoft's outages Amazon's own online public dashboard was down along with many of Amazon's customer facing services, e.g. Amazon Fire tablets.

From Amazon's post mortem "we have changed the SHD administration console to run across multiple AWS regions."

Amazon, hadn't you thought of this before? What else have you overlooked?

Sunday, May 23, 2021

Saleforce's Circular Dependency

I follow cloud vendors' outages. Broadly, I believe that cloud vendors can deliver higher availability than most SMBs can do themselves. Enterprises are a different discussion.

But I always get a kick of looking at various cloud vendors post mortem reports (archive.is).

Recently Salesforce had a DNS outage. Like other vendors, e.g. Microsoft, the Salesforce outage even took down their status page!
And look at the spin they tried to put on it.
"We're not blaming one employee," said Chief Availability Officer Darryn Dieken.
And then they threw him under the bus.
"For whatever reason that we don't understand, the employee decided to do a global deployment," Dieken went on.
They don't understand?

But wait, there's more...
"In this case," he went on, "we found a circular dependency where the tool that we use to get into production had a dependency on the DNS servers being active."
 
If you're going to run a cloud service, you've GOT to design to avoid these kinds of problems.

Sunday, November 24, 2019

But Can You Do Better Than This

If you've been reading this blog, you know that I worry about cloud availability.

However, most of the time the big cloud providers have more availability and redundancy capability than almost any enterprise can provide.

For an example, Microsoft recently had an outage of its Multifactor Authentication (MFA) for Azure and Office 365 users in North America,

There's a report on it here. And here's Microsoft's Root Cause Analysis.


Go read the Next Steps. Here's #1:
  1. Fine-grained fault domain isolation work has been accelerated. This work builds on the previous fault domain isolation work which limited this incident to North American tenants. This includes:
  • Additional physical partitioning within each Azure region.
  • Logical partitioning between authentication types.
  • Improved partitioning between service tiers.
Do you think your enterprise could add "Additional physical partitioning," "Logical partitioning between authentication types," and "Improved partitioning between service tiers?"

If you could, you must be in the Fortune 100. And that's just the first bullet of actions.

These outages from the cloud providers get a lot of publicity but unless you're a mega-scale enterprise any of them are way more capable than you'll ever hope to be.